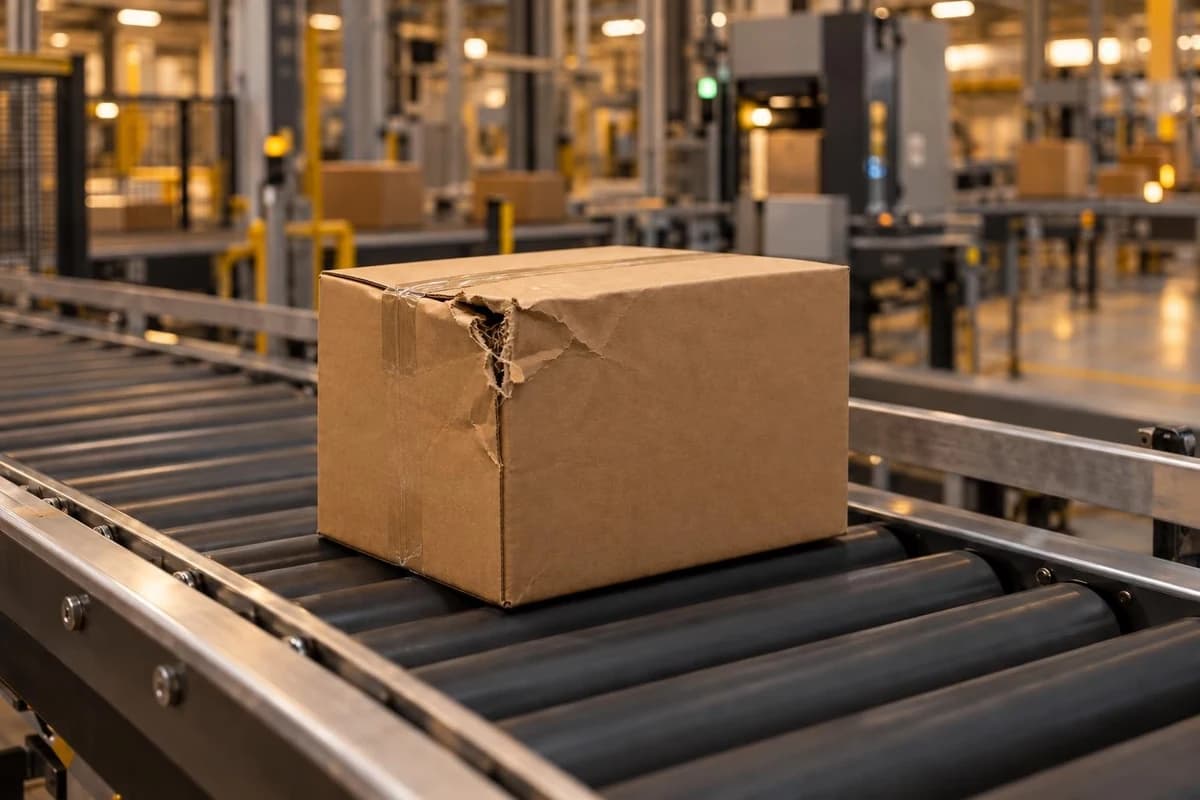
Everyday photo
Parcel condition
Question: Is the parcel visibly damaged?
- A. yesCorrect
- B. no
Correct answer: A. yes
Source: Synthetic image created for ImageJevBench · public item promo-parcel-01
Hosting = where inference runs; company = where the provider or lab is registered.
EU hosting means the route's inference runs inside the EU: an EU region, AWS Bedrock's EU cross-region (geo) profiles, Azure's Europe Data Zone, or a provider whose entire public fleet is documented as EU-hosted, each checked per model against the provider's documentation. Global deployments do not count, and neither does an EU billing region, an EU company or an EU control plane on its own. One disclosed company-policy exception stays in, marked “EU equivalent”.
Evidence requirements (benchmark evidence, priced provider, measured task tokens) sit above the table they apply to.
Applies to price views & model offers; benchmark evidence stays unfiltered.
Image benchmark · v0.1
A held-out comparison of systems that make decisions from images, from interface targets to everyday scenes.
The frozen benchmark has 684 scored items: 228 public and 456 sealed; 93 further items are retired and not scored. This page shows aggregate sealed results only. It contains no sealed task, image, answer key, or per-item prediction.
Caveat: The 333 fresh sealed items are our own synthetic images and renders. They are easier for frontier API models than the older real-source items, so sealed accuracy is higher than on the earlier split for most hosted systems.
Whole benchmark, 684 decisions. Bars include all 12 systems. Pink bars are hosted APIs; Gemma used Autoloops and no provider no-retention claim is made. A system whose Cost or Calibration axis falls under the gate scores 0; the row says which gate it is.
PQ2_0 + Q8_0 MMProj19.26Ranked by the composite score: equal-weight Intelligence, Calibration, Speed and Cost axes, then the unchanged Jev-class gates. Matched gap is signed public-minus-sealed accuracy within the matched families. No system currently exceeds the 15 pp allowance. Hosted systems are marked API because their providers received sealed images and questions; the Gemma 4 endpoint is identified separately in the exposure note.
| # | System | Composite | Intelligence | Calibration | Speed | Cost | Gap (matched) | Earlier split | Public accuracy | Sealed accuracy | USD / 1,000 | p50 / p95 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 1 | Jev-Omni | 73.10 | 63.93 | 89.90 | 89.68 | 59.52 | -1.0 pp | #3 · 55.63 | 153/228 · 67.1% | 368/456 · 80.7% | USD 0.0224 | 0.076 s / 0.103 s |
| 2 | Mapika decider-2b-vision BF16 | 66.77 | 52.84 | 81.46 | 88.17 | 57.59 | -4.4 pp | #1 · 70.02 | 151/228 · 66.2% | 319/456 · 70.0% | USD 0.0259 | 0.091 s / 0.154 s |
| 3 | Reflex 4Breleased stable configuration | 65.38 | 63.34 | 83.68 | 86.14 | 49.35 | -0.6 pp | #2 · 68.10 | 184/228 · 80.7% | 333/456 · 73.0% | USD 0.0488 | 0.154 s / 0.191 s |
| 4 | djev-spark NVFP4 | 49.38 | 49.10 | 84.30 | 83.51 | 45.95 | +3.4 pp | #5 · 41.56 | 146/228 · 64.0% | 307/456 · 67.3% | USD 0.0633 | 0.173 s / 0.374 s |
| 5 | Autoloops – Gemma 4 31B ITAPI | 47.14 | 79.27 | 82.38 | 73.89 | 42.65 | +0.7 pp | #4 · 45.91 | 193/228 · 84.6% | 397/456 · 87.1% | USD 0.0816 | 1.425 s / 2.868 s |
| 6 | djev-dev BF16 | 46.64 | 49.60 | 78.02 | 83.00 | 44.69 | +6.6 pp | #6 · 38.76 | 153/228 · 67.1% | 302/456 · 66.2% | USD 0.0698 | 0.193 s / 0.392 s |
| 7 | Bonsai-2-27B v2 PQ2_0 + Q8_0 MMProj | 19.26 | 74.91 | 90.71 | 73.62 | 29.43 | +1.9 pp | #7 · 18.95 | 191/228 · 83.8% | 379/456 · 83.1% | USD 0.2252 | 0.799 s / 1.167 s |
| 8 | GPT-6 Lunalow reasoning effort Setting: OpenRouter reasoning.effort=low Cost receipts cover 91.8% of calls API | 16.06 | 81.10 | 88.31 | 65.70 | 27.48 | +12.0 pp | #8 · 16.51 | 203/228 · 89.0% | 395/456 · 86.6% | USD 0.2166 | 2.905 s / 9.256 s |
| 9 | GPT-5.6 Luna Cost receipts cover 99.6% of calls API | 11.05 | 91.81 | 95.78 | 62.58 | 23.49 | -0.8 pp | #9 · 12.57 | 211/228 · 92.5% | 436/456 · 95.6% | USD 0.3524 | 2.878 s / 19.176 s |
| 10 | Gemini 3.1 Flash LiteAPI | 9.58 | 84.28 | 91.44 | 64.49 | 22.31 | -0.2 pp | #10 · 9.24 | 194/228 · 85.1% | 419/456 · 91.9% | USD 0.3888 | 1.799 s / 19.775 s |
| 11 | Gemini 3.8 Flash0.0 · gated by Cost (USD 2.06 per 1,000 decisions)API | 0.00 | 88.47 | 72.98 | 58.78 | 0.58 | +0.8 pp | #11 · 0.00 | 202/228 · 88.6% | 430/456 · 94.3% | USD 2.0599 | 4.832 s / 27.423 s |
| 12 | OpenJev 4B NLI v2official image-premise path0.0 · gated by Calibration (no probabilities reported) | 0.00 | 63.58 | 0.00 | 79.54 | 40.89 | +3.9 pp | #12 · 0.00 | 187/228 · 82.0% | 331/456 · 72.6% | USD 0.0934 | 0.317 s / 0.634 s |
Search any two measured systems. The radar uses the same four 0–100 score axes as the ranking; further out is better.
| Axis | Jev-Omni | Mapika decider-2b-vision BF16 |
|---|---|---|
| Intelligence | 63.9 | 52.8 |
| Calibration | 89.9 | 81.5 |
| Speed | 89.7 | 88.2 |
| Cost | 59.5 | 57.6 |
These eight examples are from the public split. Each card shows the image, question, options and correct answer; licensed sources are credited below their image.
Everyday photo
Question: Is the parcel visibly damaged?
Correct answer: A. yes
Source: Synthetic image created for ImageJevBench · public item promo-parcel-01
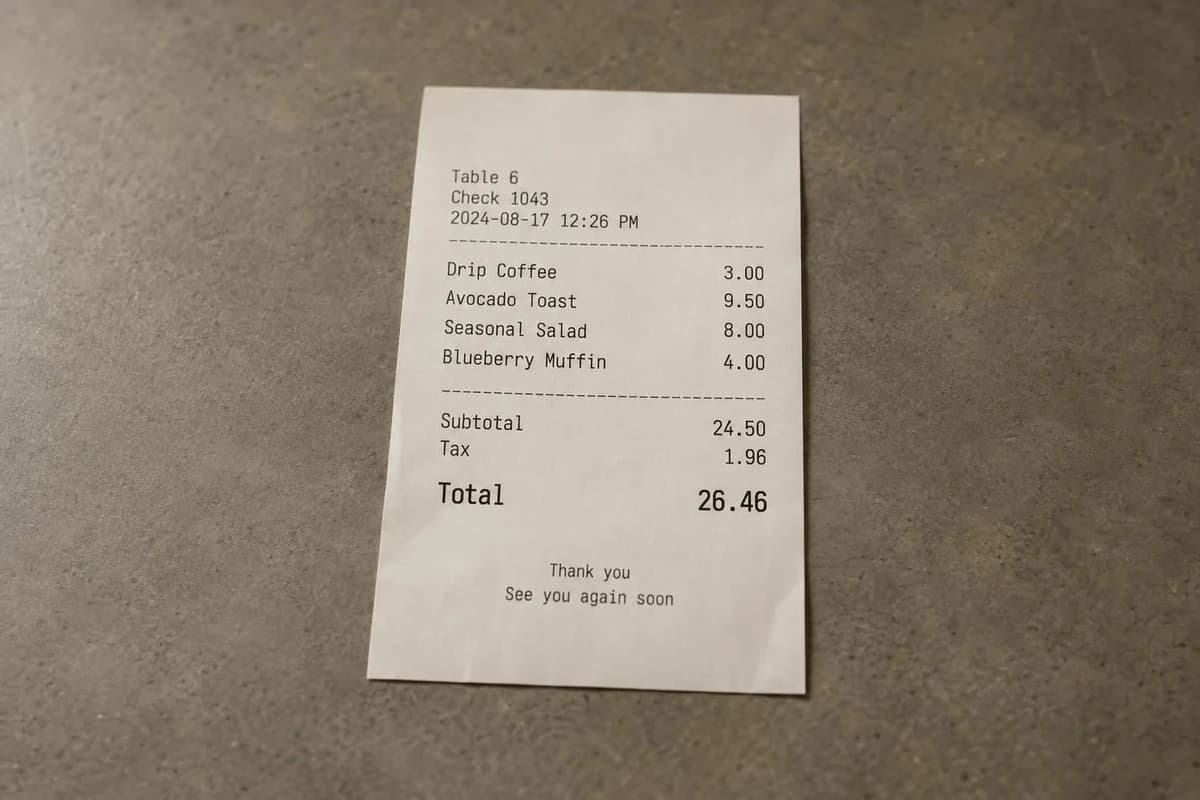
Everyday photo
Question: Is the receipt readable?
Correct answer: A. yes
Source: Synthetic image created for ImageJevBench · public item promo-receipt-00
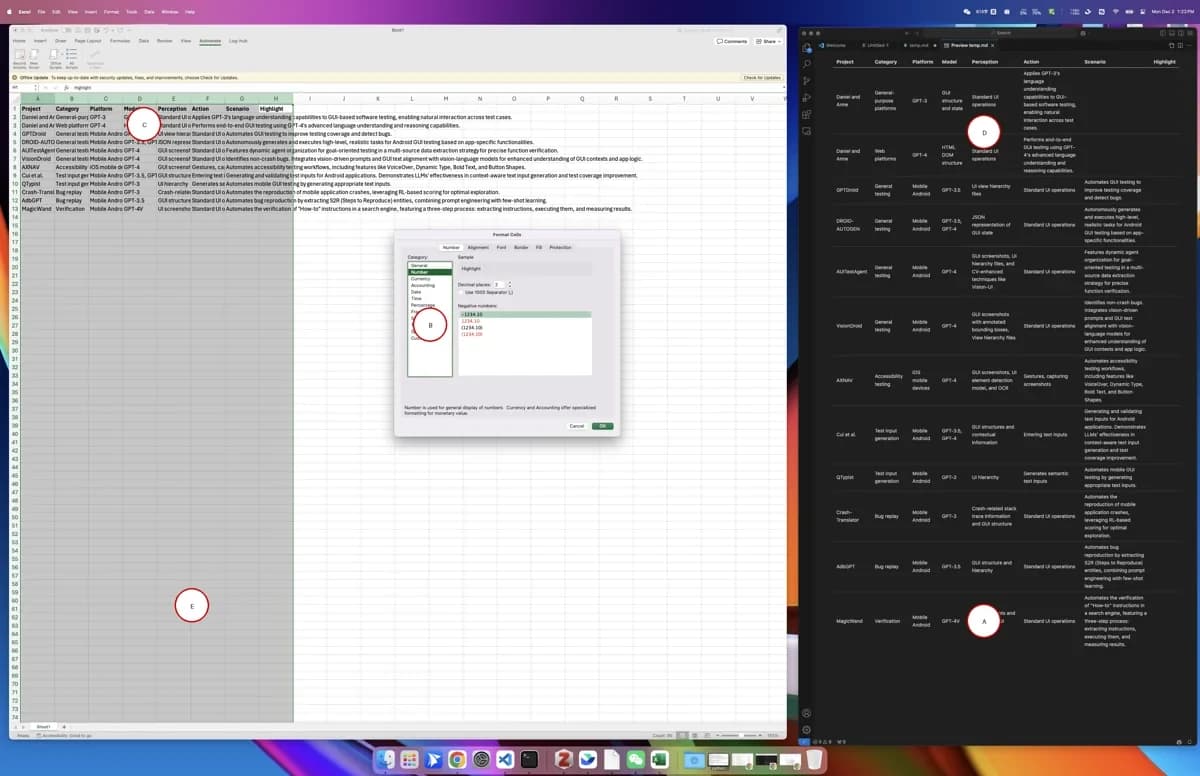
Computer use · spreadsheet
Question: Goal: change selected cells to type “Text”. Which labelled marker should be clicked?
Correct answer: B. Click marker B
Source: ScreenSpot-Pro · excel_macos_0 · MIT · 210e78d38442 · public item mm-195 · Licence text: MITAdapted: five labelled click markers were drawn on the source screenshot.
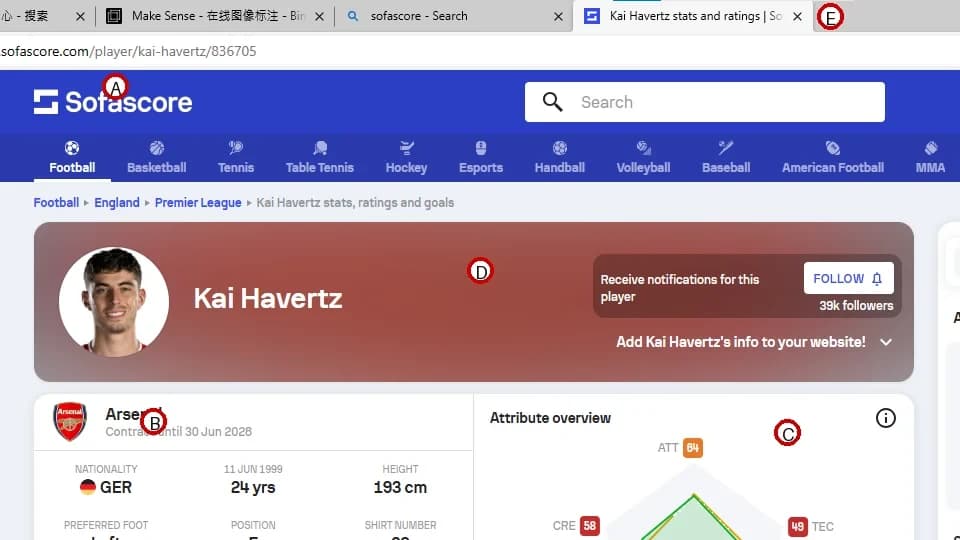
Browser
Question: Goal: open a new tab. Which labelled marker should be clicked?
Correct answer: E. Click marker E
Source: ScreenSpot · item 15 · Apache-2.0 · 0be08781e2e1 · public item mm-135 · Licence text: Apache-2.0Adapted: five labelled click markers were drawn on the source screenshot.
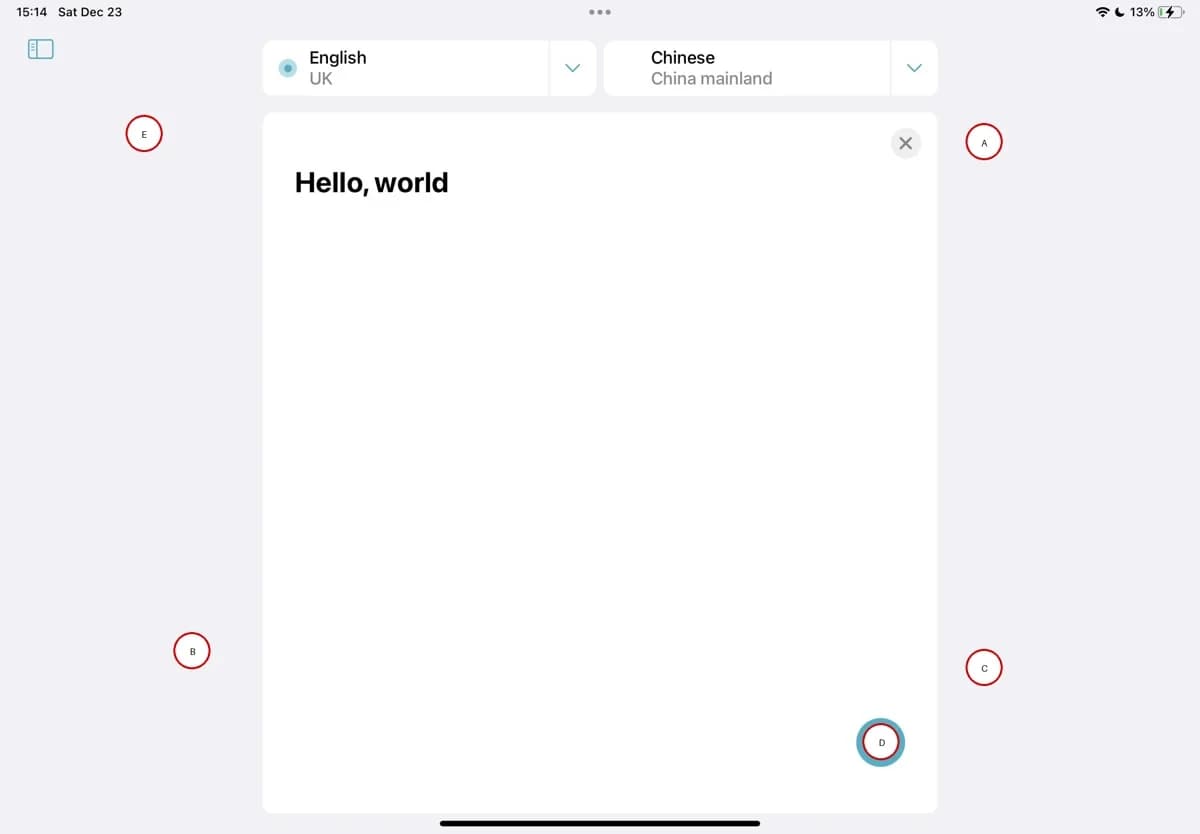
Mobile app · translation
Question: Goal: translate. Which labelled marker should be clicked?
Correct answer: D. Click marker D
Source: ScreenSpot · item 341 · Apache-2.0 · 0be08781e2e1 · public item mm-118 · Licence text: Apache-2.0Adapted: five labelled click markers were drawn on the source screenshot.
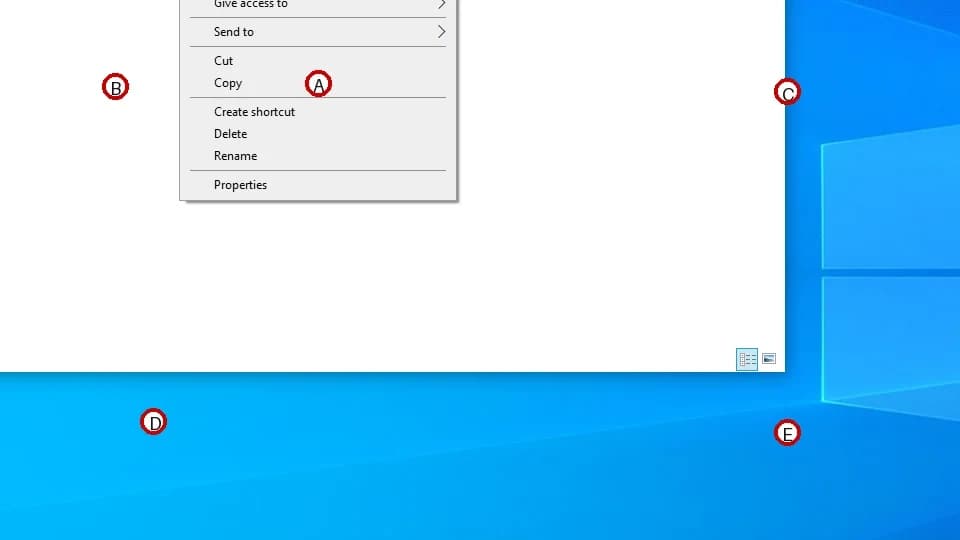
Computer use · file manager
Question: Goal: copy the file. Which labelled marker should be clicked?
Correct answer: A. Click marker A
Source: ScreenSpot · item 19 · Apache-2.0 · 0be08781e2e1 · public item mm-139 · Licence text: Apache-2.0Adapted: five labelled click markers were drawn on the source screenshot.
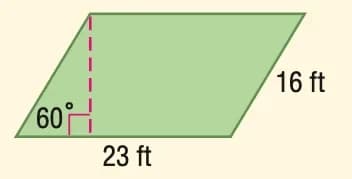
Geometry
Question: Find the perimeter of the parallelogram.
Correct answer: A. 78
Source: Geometry3K · source item 8 (public item mm-029) · MIT · fd21e533e1e5 · public item mm-029 · Licence text: MIT
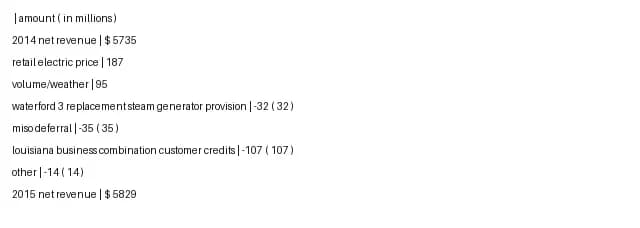
FinQA · financial table
Question: What is the net change in net revenue during 2015 for Entergy Corporation?
Correct answer: C. 94
Source: FinQA · table item · MIT annotations; CDLA-Permissive-1.0 table data · 3d6a736bc67e · public item mm-061 · Licence text: MIT, CDLA-Permissive-1.0Table data: IBM FinTabNet (CDLA-Permissive-1.0). The table was re-rendered as an image by ImageJevBench; no original filing page is shown.
Screenshot images are adapted from the credited datasets (labelled markers added); the FinQA table is re-rendered by ImageJevBench. Licences: Apache-2.0 (ScreenSpot), MIT (ScreenSpot-Pro, Geometry3K, FinQA annotations), CDLA-Permissive-1.0 (FinTabNet table data). App and website content shown in screenshots belongs to its respective owners. No Mind2Web or Android-in-the-Wild image is shown.
Each track is ranked on its own public and sealed items. The licensed core and synthetic everyday-photo results remain separately visible.
139 public · 361 sealed: 62 real-source items and 299 fresh synthetic pool items (documents, charts, inventory, safety).
| # | System | Composite | Intelligence | Calibration | Speed | Cost | Public accuracy | Sealed accuracy | USD / 1,000 |
|---|---|---|---|---|---|---|---|---|---|
| 1 | Jev-Omni | 69.71 | 55.96 | 87.32 | 89.67 | 59.17 | 71/139 · 51.1% | 276/361 · 76.5% | USD 0.0230 |
| 2 | Reflex 4Breleased stable configuration | 65.75 | 59.22 | 82.52 | 86.50 | 49.90 | 103/139 · 74.1% | 249/361 · 69.0% | USD 0.0468 |
| 3 | Mapika decider-2b-vision BF16 | 54.83 | 46.29 | 78.59 | 88.57 | 59.09 | 75/139 · 54.0% | 234/361 · 64.8% | USD 0.0231 |
| 4 | Autoloops – Gemma 4 31B ITAPI | 45.99 | 75.10 | 76.49 | 75.04 | 42.62 | 107/139 · 77.0% | 305/361 · 84.5% | USD 0.0818 |
| 5 | djev-spark NVFP4 | 32.16 | 41.11 | 80.26 | 83.55 | 45.81 | 67/139 · 48.2% | 224/361 · 62.0% | USD 0.0640 |
| 6 | djev-dev BF16 | 29.98 | 41.36 | 72.41 | 83.04 | 44.55 | 71/139 · 51.1% | 220/361 · 60.9% | USD 0.0705 |
| 7 | Bonsai-2-27B v2 PQ2_0 + Q8_0 MMProj | 18.95 | 68.86 | 87.67 | 74.16 | 29.48 | 103/139 · 74.1% | 286/361 · 79.2% | USD 0.2243 |
| 8 | GPT-6 Lunalow reasoning effort Setting: OpenRouter reasoning.effort=low Cost receipts cover 90.6% of calls API | 17.10 | 76.62 | 84.82 | 66.92 | 28.33 | 114/139 · 82.0% | 310/361 · 85.9% | USD 0.1955 |
| 9 | GPT-5.6 Luna Cost receipts cover 99.6% of calls API | 10.90 | 89.58 | 94.00 | 63.08 | 23.40 | 122/139 · 87.8% | 342/361 · 94.7% | USD 0.3550 |
| 10 | Gemini 3.1 Flash LiteAPI | 9.06 | 79.41 | 85.56 | 65.17 | 21.96 | 105/139 · 75.5% | 324/361 · 89.8% | USD 0.3994 |
| 11 | Gemini 3.8 Flash0.0 · gated by Cost (USD 2.24 per 1,000 decisions)API | 0.00 | 85.11 | 73.67 | 59.41 | 0.00 | 113/139 · 81.3% | 336/361 · 93.1% | USD 2.2351 |
| 12 | OpenJev 4B NLI v2official image-premise path0.0 · gated by Calibration (no probabilities reported) | 0.00 | 60.06 | 0.00 | 80.20 | 41.25 | 104/139 · 74.8% | 251/361 · 69.5% | USD 0.0909 |
89 public images from the promo set; 95 sealed: 61 variants from the reviewed v0.1 candidate pool across 17 matched situations and 34 fresh pool photos. Ambiguous labels were dropped after visual, two-model and gold-blind human checks. No brands and no focused faces.
| # | System | Composite | Intelligence | Calibration | Speed | Cost | Public accuracy | Sealed accuracy | USD / 1,000 |
|---|---|---|---|---|---|---|---|---|---|
| 1 | Jev-Omni | 79.86 | 90.77 | 87.74 | 89.74 | 60.50 | 82/89 · 92.1% | 92/95 · 96.8% | USD 0.0207 |
| 2 | Mapika decider-2b-vision BF16 | 73.23 | 77.11 | 85.15 | 87.25 | 54.20 | 76/89 · 85.4% | 85/95 · 89.5% | USD 0.0336 |
| 3 | Reflex 4Breleased stable configuration | 64.10 | 79.61 | 80.73 | 86.06 | 47.96 | 81/89 · 91.0% | 84/95 · 88.4% | USD 0.0543 |
| 4 | djev-spark NVFP4 | 59.72 | 76.79 | 91.38 | 83.47 | 46.34 | 79/89 · 88.8% | 83/95 · 87.4% | USD 0.0615 |
| 5 | djev-dev BF16 | 55.52 | 77.77 | 87.86 | 82.97 | 45.05 | 82/89 · 92.1% | 82/95 · 86.3% | USD 0.0679 |
| 6 | Autoloops – Gemma 4 31B ITAPI | 49.44 | 93.82 | 87.91 | 73.27 | 42.73 | 86/89 · 96.6% | 92/95 · 96.8% | USD 0.0811 |
| 7 | Bonsai-2-27B v2 PQ2_0 + Q8_0 MMProj | 19.89 | 96.64 | 93.52 | 72.38 | 29.29 | 88/89 · 98.9% | 93/95 · 97.9% | USD 0.2275 |
| 8 | GPT-6 Lunalow reasoning effort Setting: OpenRouter reasoning.effort=low Cost receipts cover 95.1% of calls API | 13.64 | 87.00 | 92.79 | 61.95 | 25.68 | 89/89 · 100.0% | 85/95 · 89.5% | USD 0.2712 |
| 9 | GPT-5.6 Luna Cost receipts cover 99.5% of calls API | 11.43 | 98.70 | 96.54 | 61.76 | 23.73 | 89/89 · 100.0% | 94/95 · 98.9% | USD 0.3451 |
| 10 | Gemini 3.1 Flash LiteAPI | 10.89 | 100.00 | 92.93 | 61.79 | 23.31 | 89/89 · 100.0% | 95/95 · 100.0% | USD 0.3601 |
| 11 | Gemini 3.8 Flash0.0 · gated by Cost (USD 1.58 per 1,000 decisions)API | 0.09 | 98.70 | 70.41 | 57.60 | 4.01 | 89/89 · 100.0% | 94/95 · 98.9% | USD 1.5839 |
| 12 | OpenJev 4B NLI v2official image-premise path0.0 · gated by Calibration (no probabilities reported) | 0.00 | 75.93 | 0.00 | 79.53 | 39.98 | 83/89 · 93.3% | 80/95 · 84.2% | USD 0.1002 |
djev-spark sealed photo result: 83/95 sealed decisions · 87.4%. It saw the public promo images in an earlier inference-only video run, with no training; this sealed score is the independent measurement for it.
The split is 228 public / 456 sealed (33.3% / 66.7%). The public part is unchanged. The sealed part is 123 never-exposed v0.1 items plus 333 fresh items from our private synthetic rotation pool, and all 12 systems were re-run on the fresh items with their original settings. 93 legacy items are retired and not scored. Split counts and hashes were frozen and posted before any system saw a fresh item.
Public / sealed split
228 / 456
33.3% public · 66.7% sealed · was 228 / 216
Licensed real-source items
201 items
139 public · 62 sealed · 93 retired
Fresh sealed items
333 items
Our own synthetic renders and photos · 299 core · 34 everyday photos
Synthetic share
70.6%
483/684 scored items are our own synthetic content
Public means an item was already exposed anywhere. That includes all 79 Mind2Web-derived items because Kev's training data overlaps Mind2Web; the 89 promo photos shown in videos; the 8 example cards on this page and in the status video; and 61 source rows in the public site repository since the 21 Sep preview. The split also counts 1 image asset already present in that repository. Every scored item that has never been exposed is sealed.
Sealed is 123 never-exposed v0.1 items plus 333 fresh items drawn from our private synthetic rotation pool (documents, charts, inventory and safety scenes, and everyday photos). The draw was stratified by family and difficulty with a seeded draw, and the split counts and hashes were frozen before any system saw a fresh item. Computer Use and Browser Use pool items were excluded because those tracks stay separate. Existing item-level outputs are reused for the public and kept sealed items; every system was run on the fresh items with the same code, pinned revisions, prompts and settings as its original run.
Retired. 93 items (ScreenSpot 45, ScreenSpot-Pro 31, Android-in-the-Wild 17) were moved from public to sealed on 24 Sep while their inputs and every system's predictions sat outside the sealed store, so they cannot count as an unseen holdout. They are not scored and not relabelled.
| Family | Public | Sealed | Retired |
|---|---|---|---|
| Android-in-the-Wild (AITW_Single mirror) | 0 | 11 | 17 |
| Everyday photo | 89 | 95 | 0 |
| FinQA | 20 | 0 | 0 |
| Geometry3K | 19 | 0 | 0 |
| Multimodal-Mind2Web | 79 | 0 | 0 |
| Pool: charts | 0 | 79 | 0 |
| Pool: documents | 0 | 102 | 0 |
| Pool: inventory | 0 | 61 | 0 |
| Pool: safety inspection | 0 | 57 | 0 |
| ScreenSpot | 20 | 29 | 45 |
| ScreenSpot-Pro | 1 | 22 | 31 |
| Total | 228 | 456 | 93 |
Two planned tracks extend the image benchmark to computer and browser interactions.
Computer Use
400 items
147 public · 253 sealed
Public decision types
Sealed decision types
Sealed origin: original synthetic local fixtures
Browser Use
400 items
240 public · 160 sealed
Public decision types
Sealed decision types
Sealed origin: original synthetic local fixtures
Cross-track sealing rule. A public-origin Computer Use or Browser Use row that shares a source row or screenshot with a sealed core item is sealed too.
Kev / Mind2Web flag. 133 Mind2Web-derived Browser Use rows are public-only and reported separately for Kev, whose training data overlaps Mind2Web.
Not measured yet — no scores. Neither track has a reviewed system or reusable output. Computer Use has no reviewed candidate in the current queue. Browser Use has one candidate requested, not yet evaluated: kev-0.6b-browser-use. Its public, ungated HF adapter is pinned at 08414b0001f6eba32bc69372abfeac5b74718ac0 (model card license: Apache-2.0), with base jaredpalmer/kev-0.6b at dece6dba8d43f0f7ded45e9f5b9df12474d90843. The model takes textual DOM state and uses a pointer head; its serving path and safe head loader are not independently reviewed. Its Mind2Web-derived examples remain public-only. Both tracks still lack a ready matched-family split and measurements, so they remain separate, requested, and unscored outside the core ranking.
Intelligence. Accuracy counts missing, invalid and unparseable answers as wrong. Each part is chance-corrected against its own average chance rate, then combined as 35% public and 65% sealed. Calibration uses the same weights.
Matched-family overfit penalty. The gap is public accuracy minus sealed accuracy within families that have at least 10 items on both sides: ScreenSpot and Everyday photo. If that matched gap is above 15 percentage points, Intelligence is multiplied by max(0, 1 − (gap − 15)/100). The same rule applies to every system. The raw overall gap is shown in the data but does not affect the score.
Calibration. Ten-bin top-label ECE is scaled by valid probability coverage. Label-only output receives zero calibration. OpenJev's NLI entailment values select an answer but are not treated as categorical probabilities.
Speed and cost. These rules are unchanged. Speed uses whole-call p50 and p95 latency; local latency uses the v1.4 2× plus 0.15-second adjustment. Hosted unit cost uses returned per-call usage receipts; missing receipts are not zero-filled, and the Cost axis is scaled by receipt coverage. Retry costs are tracked separately. Local cost uses measured GPU seconds at the recorded per-system GPU-hour rate and excludes loading, downloads, build, and idle time. For self-hosted systems, the original run's timings are combined with the fresh-item run on the same GPU type.
Composite and gates. These rules are unchanged. The four axes use an equal-weight harmonic mean, followed by the Jev-class Intelligence, Speed, and Cost gates below 50. Gemini 3.8 Flash's high raw accuracy but near-zero composite reflects its measured cost and the Cost gate; label-only systems have zero Calibration under the inherited convention.
Difficulty balance. The split follows exposure, not a stratified draw, so the parts differ in family mix: browser actions (Mind2Web), chart questions (FinQA) and geometry are public-only, while ScreenSpot-Pro, Android-in-the-Wild and the fresh pool families are sealed-only. This is why the overfit penalty compares only matched families (ScreenSpot and Everyday photo).
Fresh-item difficulty. The 333 fresh sealed items are our own synthetic images and renders. They are easier for frontier API models than the older real-source items, so sealed accuracy is higher than on the earlier split for most hosted systems. Scores on this split are therefore not comparable with the earlier 228/216 preview.
Exposure. GPT-6 Luna and Gemini 3.8 Flash previously saw public promo-photo candidates and sealed-photo candidates in stateless label-check calls, including candidates later dropped. The checks showed no gold; human gold-blind adjudication decided inclusion. GPT-6 Luna is the saved low-reasoning-effort setting. Four OpenRouter systems used the requested no-retention route with fallback disabled; Gemma used the Autoloops endpoint and is API-flagged, with no no-retention claim made here. Local systems ran without network, credentials, or gold maps. The fresh pool items were authored with Claude and reviewed by OpenAI Codex as a blind critic, and the pool photos were generated with an OpenAI image model. This is disclosed for the two OpenAI rows. Self-hosted systems ran the fresh items on one rented GPU pod in offline containers with read-only inputs.
The ranking covers 12 measured configurations. Gemma 4 31B reuses completed saved results on the original items and was run on the fresh items; GPT-6 Luna is the saved low-reasoning-effort setting. Candidates below have no score unless listed in the ranking. Requested rows remain visible with the exact access or review blocker; exclusions describe the reviewed interface, license or duplicate status.
| Candidate | Source revision | Access | Status | Reason |
|---|---|---|---|---|
| CUA-S1-4B-0.2 multimodal adapter | HF 16818868b | Public, ungated; pinned revision resolves | requested, not yet evaluated | Pinned source and multimodal image path passed source review; the integrated runner’s exact-hash independent review is pending. No weights have been staged and no ImageJevBench inference has run. |
| Visual Jev 4B Answer-SFT | HF 7a3f1bb0d | Public, ungated; pinned revision resolves | requested, not yet evaluated | Pinned source and image path passed source review; exact-hash runner review is pending. Training used two and four options while the benchmark includes up to five. No weights have been staged and no inference has run. |
| NeoHorse-Jev-4B | HF 56c36ae62 | Public, ungated; pinned revision resolves | requested, not yet evaluated | Pinned self-contained multimodal source passed source review; the integrated runner’s exact-hash independent review is pending. No weights have been staged and no inference has run. |
| Jevify Qwen3-VL-2B Tier 2 | HF 46e8e72c2 | Public, ungated; pinned revision resolves | requested, not yet evaluated | Pinned Tier 2 vision adapter and image path passed source review; exact-hash runner review is pending. The loader rejects an optional pickle head. No weights have been staged and no inference has run. |
| Standard One 3B | HF c0d23877e | Public, ungated; pinned revision resolves | requested, not yet evaluated | Pinned image-capable checkpoint and server path passed source review; exact-hash runner review is pending. No weights have been staged and no inference has run. |
| Standard One 8B | HF 5d1285dd7 | Public, ungated; pinned revision resolves | requested, not yet evaluated | Pinned image-capable checkpoint and server path passed source review; exact-hash runner review and a fresh pod/disk resource gate are pending. The checkpoint is about 17.9 GB and will be staged only on an owned remote pod. No weights have been staged and no inference has run. |
| Sage1 / Levanto Sage | Hosted image | API requires SAGE_API_KEY; no configured key or free grant | requested, not yet evaluated | No-cost access is unavailable. No paid quota was purchased. |
| djev-distill-v4 | 26B-class ch | No checkpoint staged | requested, not yet evaluated | Custom vLLM backend and loader review are incomplete; no model download was attempted. |
| yah01/vjev-vision | HF 2fa8b58e4 | Public, ungated | requested, not yet evaluated | Reviewed loader uses unrestricted torch.load(head.pt); safe loader review is incomplete. |
| WIlfLin/JEV-Qwen3.8-Flash-Next-Linear-Runtime | HF 1847787ff | Public model metadata; upstream weights about 184 GB | requested, not yet evaluated | License permission and a viable reviewed multi-GPU runtime remain unresolved; no weights were downloaded. |
| Visual-Jev generic Qwen3.5-4B scorer | GitHub 2d68c | Public repository | requested, not yet evaluated | This is distinct from Answer-SFT, but its exact base, runtime and optional image path lack pin-specific review. |
| divyanshx11/JEVision | HF 324698caa | Public, ungated | requested, not yet evaluated | The pointer-head .pt artifact and incomplete runtime need safe-loader and interface review. |
| SeanLiu/Jev-Vision 8B | Exact infere | Checkpoint page is public | requested, not yet evaluated | The head is a .pt artifact and its exact inference loader has not passed review. |
| Fr0zencr4nE/jev-spatial | HF 5727eade6 | Metadata public; previous anonymous weight-file inventory returned HTTP 401 | requested, not yet evaluated | No keyless weight staging path is confirmed, and the spatial specialist's general typed-choice interface is unverified. |
| Sarashina 2.2 vision JEV mmproj 3B | HF 09ce275e3 | Public, ungated | requested, not yet evaluated | The vision-language projection has no reviewed general typed-choice adapter/runtime. |
| OhtaMan Gemma 4 E2B IT choice-64 | HF 3d403b990 | Public, ungated | requested, not yet evaluated | Image-text metadata is present, but its actual choice interface and inference code are unreviewed. |
| MetaSK-Jev 4B policy mix | HF ea20fe85b | Public, ungated | requested, not yet evaluated | Image-text metadata is present, but its actual image path and typed-choice runtime are unreviewed. |
| Jevify Gemma 4 E4B | HF a6b5a716f | Public, ungated | requested, not yet evaluated | Distinct from measured hosted Gemma 4 31B; local runtime, typed interface and license review are incomplete. |
| Jevify Gemma 4 26B-A4B | HF d4c0d1d45 | Public, ungated | requested, not yet evaluated | Distinct from measured hosted Gemma 4 31B; local runtime, typed interface and license review are incomplete. |
| JevAny-27B-SFT | HF ad7b48b70 | Public, ungated | requested, not yet evaluated | Image/video capability is reported, but the pinned base/runtime and training-data overlap review are incomplete. |
| JevAny-27B-RLCR | HF 078883b2e | Public, ungated | requested, not yet evaluated | Distinct adapter; its pinned base/runtime and training-data overlap review are incomplete. |
| LFM2.5-VL-3B-Decision-NVFP4 | HF 1ff8bf556 | Public, ungated | requested, not yet evaluated | Image/video input is reported, but license terms, decision-head behavior and local runtime are unresolved. |
| yeyan00/Jev-Decision | GitHub eac9d | Public repository; exact checkpoint access unknown | requested, not yet evaluated | The checkpoint, image interface and inference runtime are not pinned or reviewed. |
| OmniJev 4B / 2B / 0.8B | Distinct pub | Public model pages | requested, not yet evaluated | Published loaders use unrestricted pickle .pt files; an approved safe loader is unavailable. |
| Bonsai-Llama-Jev submission (measured as Bonsai-2-27B v2) | kyr0/Bonsai- | Public pinned submission and model artifacts; completed item-level outputs reused from the Bonsai measurement job | included in ranking (rank 7/12) | This submission maps to the existing Bonsai-2-27B v2 PQ2_0 + Q8_0 MMProj row (score 18.9529). The reviewed System One path accepts inline image data; offline_eval.image_body reads each local image and sends it as a data:image data URI in the request state. The final clean run returned 444/444 image predictions. The frozen 228-public / 216-sealed roster was rescored from these saved item outputs; no rerun was done. See receipts/BONSAI-ALIAS-AND-IMAGE-PATH.md. |
| AutoJev-27B | GitHub denis | Public, ungated; Apache-2.0 weights / MIT code | requested, not yet evaluated | Pinned upstream inference source supports images: DecisionInput.images is typed; model.open_image loads image objects, data URIs or paths; DecisionModel.prepare passes images to the processor; server EvaluationRequest.images flows into model.prepare. However, this continuation has no ImageJevBench offline, local-only, safetensors adapter/controller for AutoJev. The exact-hash-reviewed runner is frozen to six other candidates pending independent PASS. A separate adapter and exact-hash review are required. The public, ungated Apache-2.0 checkpoint is about 52.2 GB and may only be staged on a remote owned pod after fresh disk, watchdog, GPU and spend checks; the current USD 6 approval covers the six-candidate proposal and has not been extended to AutoJev. No weights or task inputs were staged and no predictions were made. |
| CLM-8B | Contrastive- | Public checkpoint; text encoder | excluded from image ranking | The reviewed Engine.answer(state, {decision: question}) adapter and frozen Qwen3-8B encoder have no image argument or image processor. |
| Eikos 4B / 27B | Reviewed Let | Public checkpoint; source reviewed | excluded from image ranking | LetterAdapter.dist(state_text, question, options) receives text only; conditional-generation architecture selection is not image input. |
| Main Jev / TypeSafe | Official doc | Official API/interface; no native image field | excluded from image ranking | The documented state/decision interface accepts text, objects and arrays, with no supported image input. A wrapper field is insufficient. |
| OpenJev-Vision | GitHub b83be | Public repository | excluded from core ranking | The published fixed classifier/head does not expose the general typed dynamic-option interface used by the benchmark. |
| hr98w/jev-visual | GitHub 4382b | Public repository | excluded as a duplicate wrapper | A request/runtime wrapper, not a distinct checkpoint or decision head. |
| Qevi-2B and Laya Vision 201M/256M | Candidate sw | Public model pages; non-commercial terms | excluded pending license clearance | Existing review reports non-commercial or non-commercial/share-alike terms; public-release permission is not established. |
| Jev-Omni reuploads and quantizations | Candidate sw | Public reuploads | excluded as duplicates | No distinct model family/runtime is established beyond the already measured Jev-Omni row. |
| joyfox/Qwen3.5-0.8B-JEV | Candidate sw | Public checkpoint | excluded from image ranking | The decision artifact removes the vision tower; text-only. |
| Hanno-Labs/bosun-v3.1 0.6B / 1.7B | Candidate sw | Public checkpoint | excluded from image ranking | Qwen3 text decision models; no image path documented in the reviewed release. |
| autotrust/JEV | Candidate sw | Public source | excluded from image ranking | Typed text/JSON decisions only; no image input documented in the reviewed interface. |
| Programalyst/realtime-vision-decision-agent | Candidate sw | Public repository | excluded as an application wrapper | Combines vision detection with Jev but is not a distinct model checkpoint. |
Image JevBench is a separate benchmark from the text-only JevBench Score. Sealed item-level content remains private. Public/sealed item counts, accuracy, track and score breakdowns are aggregates. Results describe these exact tested configurations and do not establish absence from model training data.